
Is it safe to give AI your designs and customer lists?
Once an AI has learned a secret, you may not be able to take it back
Practical Guides: Part 2
An employee used a company circuit design with an AI agent: that is Apple’s allegation. Apple told the court that training on confidential material could cause damage that is very difficult to undo. The concern also applies to customer names and inquiry histories. What happened, why can removal be difficult, and what should your organization do? This guide explains the issues in plain language.
When information leaks, asking for the file to be returned or deleted has traditionally been part of the response.With AI, that may not undo all of its effects.On August 31, 2026, Apple raised this concern in its litigation involving OpenAI. The article’s account centers on one circuit-design file and a former employee’s description of an AI agent having learned a task.
- What you will learn: 1 What Apple alleged could be irretrievable in its litigation involving OpenAI
- What you will learn: 2 Why removing designs or personal information incorporated into a model can be difficult
- What you will learn: 3 How to use AI while keeping confidential information inside your organization
The key idea
Training changes the numerical parameters inside an AI model using the material it receives. Once incorporated, the material cannot simply be taken out as a separate document.Providing a reference is like putting a document on a desk for someone to consult; removing it stops that consultation, though copies can remain. Training is more like dissolving onions into a curry: you cannot simply lift out the original onions afterward. Designs and customer names can both influence the model.
What did Apple argue could not be recovered in its OpenAI lawsuit?
The case is in a federal district court in California.The following account describes Apple’s allegations, which OpenAI and the former employee dispute.This is a dated account, not a finding of liability or a statement of the case’s current outcome. Read the chronology with that distinction in mind.
He joined OpenAI, which was moving into AI hardware development.Reports described approximately 400 former Apple employees joining OpenAI; this was background reporting, not a finding of wrongdoing
It was a text-based file that could be opened with a free circuit simulator.The account raises the issue of cloud access remaining after employment ends
The article reports that he described an AI agent learning to run simulations and interpret results, reducing a day’s work to about two hours.A design file used with an AI workflow raises a further question: was it also used to train a model?
OpenAI disputed the allegations and, according to the cited reporting, argued that Apple had created the situation and that it had not received Apple’s secrets.The company hiring the employee was also named as a defendant
Its concern was that if an AI model learned the secret, the use could become irreversible and continue to spread. At a minimum, Apple argued, that harm would be exceptionally difficult to undo.Apple relied on declarations from a forensic expert and an electrical-engineering professor
The article did not establish whether model training had actually occurred.That uncertainty was one reason Apple sought expedited discovery
Why learned information can be difficult to remove: three reasons
Training does not keep each source as a separate file
When an AI consults a document, the source remains outside the model; it can be removed from retrieval, though copies and logs still matter. Training is different. Its influence is distributed across the model’s many numerical parameters, without a simple location corresponding to that one document. Apple’s expert described how a design used for training or refinement can become part of a model, making its subsequent use harder to trace.
In practical terms: The onion has mixed into the curry. There is no ordinary document-level Delete button for its influence on the model.
Apparent forgetting may not be permanent
Targeted unlearning remains an active research area. A study presented in 2025 found that 4-bit quantization substantially restored supposedly forgotten knowledge for the constrained methods tested. Other experiments found recovery after limited fine-tuning. Results vary by method, model and task, so these are not proof that every technique fails. Retraining without the disputed data is a reference approach, but for a large model it can be very expensive.
In practical terms: Some methods behave more like covering information than erasing it. Test whether the apparent removal survives later changes.
Information can spread while its original form disappears
Learned information can influence later answers. Those answers may inform revised designs; a model may be copied, or its outputs used in training another model. As this happens, the result can look progressively less like the original file. Meanwhile, logs and other evidence can be overwritten in ordinary operation. These are possible propagation paths, not a claim that every answer contains the secret.
In practical terms: Someone tastes a dish, recreates something similar at home, and another person adapts that version. After several iterations, the result may barely resemble the original recipe even though it began there. As time passes, proving the connection can become harder.
Can personal information also become part of an AI model?
Yes. Training can incorporate personal information as well as designs.And the consequences can be especially difficult to manage.A design dispute may involve one company’s rights. A customer list can affect many individuals, each with rights that may include requesting cessation of use or deletion where the applicable legal conditions are met.
A deletion request may be difficult to fulfill
Consider customer lists, inquiry histories, job applicants’ records or patient information pasted into cloud AI for summarization. If the provider actually uses those inputs for training, deleting the source or chat may not remove the resulting model influence. A later request from an affected person therefore cannot be answered responsibly with a simple assurance that everything has been deleted.
In practical terms: A leaked design may affect a business partner. A leaked list can affect every person named in it.
Japanese guidance already requires checking how personal data is used
On June 2, 2023, Japan’s PPC warned that supplying personal data without prior consent may violate the APPI when it is used beyond generating the requested answer, including for training. Its guidance asks organizations to adequately confirm that the provider will not use that personal data for machine learning.
The amendment enacted in July 2026 introduces a conditional exception for processing solely to produce statistical information and qualifying AI development. It also establishes an administrative monetary-penalty framework for specified serious violations. These provisions are subject to commencement and implementing rules; enactment does not mean they were already in operation when this article was published. Ordinary prompt entry is not automatically covered by the statistical exception, and the penalty conditions are more specific than a simple headcount threshold.
In practical terms: Check who controls the processing and the lawful basis before sending data. The amendment does not turn routine prompt entry into unrestricted use.
A US regulator has required deletion of models as well as data
In 2021, the US Federal Trade Commission finalized a settlement concerning a photo-app developer’s alleged misuse of facial-recognition technology. Deleting the source photographs was not the only requirement: the order also required deletion of covered models and algorithms developed using affected users’ photos or videos. The broader lesson is that a remedy can reach the model produced from improperly used data, not just the input files.
In practical terms: Improper use of personal information can put the resulting AI model itself at risk.
Why this matters to your company
This is not a concern reserved for the largest technology companies. The story involves a design file readable with free software and an employee trying to finish work faster. Drawings, formulations, recipes, mold data, cost sheets and customer lists: your company’s confidential information may take the same forms.The risk can arise from three different directions.
An employee sends data to AI with good intentions
An employee pastes a drawing or customer list into a personally subscribed AI service. There need be no malicious intent; the aim is to finish sooner. Yet the employee may not understand or control the service’s training settings and terms. The company may not even know the transfer occurred.
A new employee brings a former employer’s data
The receiving company can also become involved in litigation, as the cited case illustrates. If a new employee supplies a former employer’s information to your AI, your organization may face questions about its use. Appropriate records and onboarding controls help establish what happened; a lack of records does not prove that nothing occurred.
A ban drives use out of sight
The article reports a former employee describing a reduction from a day’s work to two hours. A tool offering that benefit is difficult to manage through prohibition alone. Employees may use it outside approved channels. The risk then becomes less visible instead of disappearing.
Common assumptions and the practical reality
| Common assumption | Practical reality |
|---|---|
| If information leaks, deleting the file restores the original position | Training can leave an influence beyond the source file.Deleting a document does not necessarily remove that influence from model parameters. |
| Unlearning technology makes this risk irrelevant | Reliable targeted removal is still challenging.Studies have found recovery after quantization or limited fine-tuning for particular tested methods; effectiveness must be validated, not assumed. |
| Turning off training makes everything safe | It helps, but relies on the applicable service controls and commitments.A corporate setting does not automatically cover employees’ personal AI accounts. |
| Personal information is less sensitive than design data | It can be particularly difficult to manage.Each affected person may have rights under applicable law, and Japanese guidance requires checking whether personal data will be used for training. |
| Japan’s 2026 amendment permits unrestricted use of personal data in AI | The statistical-processing exception is conditional and subject to commencement.It does not automatically cover routine prompt entry. The amendment also creates a monetary-penalty framework with specified conditions. |
| Banning AI protects all confidential information | Unauthorized use can move out of sight.The company may then have fewer records and weaker control over what information is entered. |
| Internal documents should never be used with AI | The key questions include where and how they are processed.An internally controlled AI lets your organization decide who can use it and when to stop it. |
Self-check: how does your company handle AI and secrets?
Select the statements that apply. This self-check does not send your selections to a server.
Eight questions about AI, confidential information and personal information
Check items to see an indicative risk level and suggested next steps.
Three steps to keep control of confidential information
- Separate reference use from model training: classify the ways your organization uses AI. If it consults documents, you can remove them from retrieval and manage retained copies. If data is used for training, plan for the possibility that targeted removal will be difficult. Decide where it happens and who controls it. Is the document on the desk, or has it gone into the cooking pot?
- Provide an approved AI environment that keeps sensitive data inside: instead of relying only on a ban, give employees an environment approved for the relevant confidential and personal information. When local processing and storage remain inside the organization, the question of an outside provider’s handling can be avoided for that workflow. Local access, retention and security controls still matter.
- Record who entered what: this is easy to overlook and essential to incident response. Apple sought urgency partly because evidence could disappear during normal operation. Individual accounts and appropriately scoped activity records can help establish the affected data and your organization’s actions. Confirm what the available audit logs actually record; login records alone do not prove every prompt’s content.
Why banning AI is not enough
Knowing what to do is only the start. Teams in design, manufacturing, quality, procurement and customer service already see AI as a way to complete work faster.
The reported account illustrates the attraction
The former employee reportedly described a day’s work taking two hours. That statement illustrates why employees want to use AI, although it is not an independently verified productivity benchmark. A practical policy must account for that incentive.
A ban can move use outside your view
If the organization provides no suitable alternative, employees may turn to a personal phone or home computer. Company records, data-entry restrictions and account revocation procedures may not cover that use.
Japanese government guidance also limits confidential inputs
The Digital Agency’s June 2026 guidelines restrict handling confidential information in cloud AI services used merely by accepting standard terms, subject to the applicable government rules. The PPC’s June 2023 alert separately asks organizations to verify that personal data is not used for machine learning. The 2026 privacy-law amendment is not blanket approval for employee prompt entry. Your drawings and customer lists deserve similarly deliberate handling.
Wanting AI to use internal knowledge is reasonable
You may want AI to draw on company drawings, past defect reports and customer-service histories so that experienced employees’ knowledge is available to the whole organization. That is a legitimate objective. The concern is losing control over sensitive information processed or trained outside your organization.
The answer is more than a prohibition. Provide an internally controlled AI environment, with appropriate records and a clear distinction between reference retrieval and model training. Employees can then use an approved tool while your organization controls where its sensitive information goes.
Why we propose AI that keeps data inside your organization
Apple’s argument illustrated how difficult it can be to undo the consequences after information leaves your control. One practical response is to keep sensitive processing inside from the start.
Sovereign GaiXer is an AI operating environment that runs on a compact appliance. After required initial setup, local models can operate on the internal network without continuous internet access. In that closed-network configuration, entered text and internal documents remain within your environment. Processing, storage and reference-document workflows stay on the appliance. The cooking pot and the kitchen remain under your organization’s control.
Use designs and customer documents without sending them to an external AI service
Sovereign GaiXer is a generative AI environment running on Lenovo ThinkStation PGX. Local AI processing, data storage and document-reference workflows run within the appliance. In a closed-network configuration, those documents are not sent over the internet.
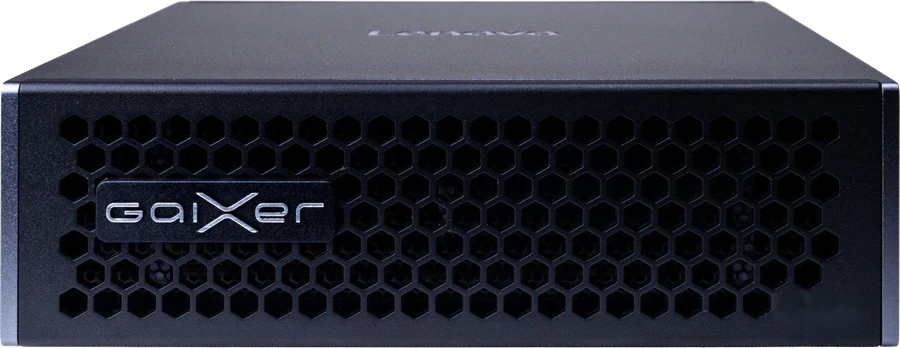
After initial setup, operates on an internal wired or Wi-Fi LAN without continuous internet access. Local use can also be configured without an external-network connection.
Features, specifications and Japan reference prices reflect published information as of September 2026. See Trust & Security for security details and Customer Stories for examples. Contact us to discuss a demonstration and availability for your location.
How three approaches compare
| Item | Employee-managed cloud AI | AI ban | AI running within your appliance |
|---|---|---|---|
| Where secrets go | An external service provider | Intended to stay inside; unapproved use may be unknown | Your internal appliance |
| Where training occurs | Depends on provider terms and settings | No approved training | Internally, if a supported training workflow is configured |
| Personal information | Provider handling must be checked; corporate visibility may be limited | No approved input; hidden use may be unknown | Stays local in a closed-network configuration |
| Records of users and activity | May not be available to the company | Hidden use may leave no company record | Individual accounts and available audit logs |
| Working speed | Can improve | Benefits forgone, or use occurs unofficially | Can improve |
| Cost model | Subscriptions or metered charges, depending on the service | Opportunity cost | Purchase plus operating costs; cost per use can fall with utilization |
A short glossary
Training (fine-tuning)
Updating an AI model’s numerical parameters using supplied material. The resulting influence is not stored as a separately removable document.
Providing references
Keeping documents outside the model and supplying relevant content when answering. Removing the source stops future retrieval, but copies, logs and retained answers also need review.
AI agent
AI that operates software or equipment to perform tasks on a person’s behalf. It may save procedures and repeat them automatically.
Machine unlearning
Techniques for removing the influence of particular training data. Some methods suppress behavior without reliably erasing the underlying information.
Trade secret
Under Japanese law, information must be managed as secret, be useful for business and not be publicly known to qualify for trade-secret protection.
Personal data
Personal information organized in a searchable database, such as a directory or customer register. Having an AI provider use it for training without a valid legal basis may violate Japanese law.
Statistical-processing exception (2026 amendment)
A conditional rule enacted in Japan in 2026 for data used solely to create statistical information and similar outputs, including qualifying AI development. Commencement and implementing requirements matter; it does not automatically authorize employees to enter personal data into prompts.
Shadow AI
AI used for work without the organization’s knowledge or approval. The company may lack records and enforceable boundaries.
On-premises
Processing and storing data on equipment at your own premises. A closed-network configuration can keep that data off the internet.
Frequently asked questions
What does it mean to train an AI?
Training changes the numerical parameters inside an AI model using the material supplied. Once information is incorporated, it cannot simply be removed as a separate document. This differs from providing a document as a reference for answering a question.
Can trade secrets learned by an AI really not be recovered?
Reliable targeted removal remains difficult. Retraining without the material is a reference approach, but can be extremely expensive. Studies of particular unlearning methods found that apparently forgotten knowledge could return after quantization or limited fine-tuning. These results do not establish that every unlearning method must fail. Apple argued that training on trade secrets could cause irreversible, continuing harm; whether training occurred in that case was disputed.
Does entering personal information into generative AI violate Japanese privacy law?
It depends on the circumstances. On June 2, 2023, Japan’s Personal Information Protection Commission warned that entering personal data without prior consent may violate the Act on the Protection of Personal Information if the service uses it for purposes beyond returning an answer, such as training. Organizations should adequately confirm that the provider will not use that data for machine learning. The July 2026 amendment introduces a conditional exception for statistical processing, subject to commencement and implementing rules. It is not blanket permission to paste personal data into a prompt.
Is disabling use of data for training in a cloud AI service enough?
It is an important step. But protection also depends on the provider’s terms, controls and evidence; it is not the same as direct control of the processing environment. Corporate settings do not automatically cover an employee’s personal account. Being able to verify the arrangement is different from simply assuming it applies.
If we train an internal AI on company documents, is that also hard to undo?
Yes, targeted removal can still be difficult. That is a reason to keep sensitive training within an environment your organization controls. With the appliance on your premises, you can decide how the model is used, when it stops and who may access it. Keep control from the outset of information that may be difficult to recover.
Is an AI agent remembering a procedure different from model training?
It can be. If an agent merely saves instructions in a file, that file can be deleted, subject to copies and retention. The issue is establishing whether the content was also used for model training. Apple sought discovery because the actual use needed investigation. Local processing and retained records can make this distinction easier to establish; they do not remove the need to investigate.
How should we address the risk of new employees bringing a former employer’s data?
Obtain a written commitment at onboarding not to bring a former employer’s confidential information or enter it into your AI. Require individual accounts for the internal AI and retain appropriate records. Those records can help establish what entered your systems if an incident occurs.
What if an employee has already entered a customer list into cloud AI?
First preserve the facts and relevant evidence, then check the service’s terms, account settings and actual handling of the input. Where appropriate, request deletion of retained content; deleting chat history alone does not prove removal from all systems. If training may have occurred, seek specialist advice promptly and assess any duty to report to the PPC or notify affected individuals. Provide an approved internal AI environment and address the cause to prevent recurrence.
Does data stay inside Sovereign GaiXer when working with company documents?
With local models and a closed-network configuration, AI processing and storage remain within the appliance. After the required initial setup, it can operate on the internal LAN without continuous internet access. External services or integrations, if enabled, need separate review. Learning Sets let the AI use internal documents as references; this does not by itself mean model fine-tuning.
Where should we start if we are considering deployment?
First list the information employees must not enter into unapproved AI services, including both design data and personal information. Bring that list to a product demonstration so you can see how the appliance handles your intended information and use cases.
Three points to remember
- Providing references is like putting a document on a desk. Training is more like mixing an ingredient into a dish. Returning or deleting the original file may not reverse its influence on a model. Apple raised that concern in its litigation; it was an allegation requiring investigation, not a finding that training had occurred.
- The same concern applies to customer information as well as designs. Individuals have rights under applicable law, and Japanese guidance asks organizations to check whether personal data will be used for training. Japan’s 2026 amendment also establishes a conditional penalty framework, subject to commencement.
- Provide a workable alternative to unapproved AI use: keep sensitive workflows inside your organization, retain appropriate records and decide explicitly whether the AI is retrieving references or undergoing training.
Sources
External sources open in a new tab. The litigation account is based on filings, including the plaintiff Apple’s allegations, and reporting. It is not a judicial finding. Japanese privacy-law references describe Japan’s framework; the 2026 amendment’s commencement and detailed rules must be distinguished from its enactment.
Court filings and reporting
- Apple Inc. v. Chang Liu, et al. (N.D. Cal. 5:26-cv-07078), Supplemental Brief in Support of Motion for Expedited Discovery, Dkt. 94-1 (August 31, 2026)
- Apple Inc. v. Chang Liu, et al. (N.D. Cal. 5:26-cv-07078), Declaration of Dr. Ayman Fayed, Dkt. 94-3 (August 31, 2026)
- Business Insider Japan, report on Apple’s claim that AI-incorporated trade secrets may be difficult to recover (September 2026; Japanese)
- MacRumors, Apple Says Former Engineer Used Stolen Trade Secrets at OpenAI, Taught AI Agent to Run Them (August 31, 2026)
- MacRumors, Dispute With OpenAI Said to Be a ‘Mess of Apple’s Own Making’ (September 1, 2026)
Personal information and policy
- Personal Information Protection Commission, Alert on the Use of Generative AI Services (June 2, 2023; Japanese)
- Personal Information Protection Commission, 2026 APPI Amendment (enacted July 10 and promulgated July 17, 2026; Japanese)
- Personal Information Protection Commission, Policy for the Three-Year Review of the APPI (January 9, 2026; Japanese)
- US Federal Trade Commission, FTC Finalizes Settlement with Photo App Developer Related to Misuse of Facial Recognition Technology (May 2021)
- Digital Agency, DS-920: Guidelines for Procurement and Use of Generative AI for the Evolution and Innovation of Public Administration (June 12, 2026; Japanese)
- Ministry of Economy, Trade and Industry, Protecting and Using Trade Secrets (Japanese)
Technical research
- Zhang et al., Catastrophic Failure of LLM Unlearning via Quantization (ICLR 2025)
- Unlearning Isn’t Deletion: Investigating Reversibility of Machine Unlearning in LLMs (first published 2025; subsequently revised)
- Liu et al., Rethinking machine unlearning for large language models (Nature Machine Intelligence, 2025)